~/projects/mafdet open source
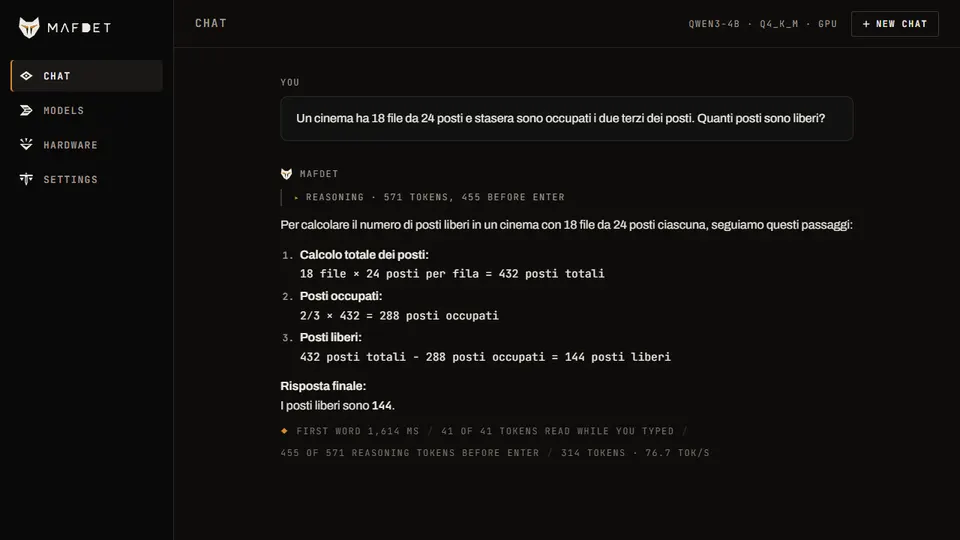
Mafdet
AI · LLM tooling · Prototype · on PyPI
Local LLM runner that reads and reasons on your message while you type, so the wait after Enter drops from 12.2 s to 3.2 s on Qwen3-4B. Built on llama.cpp with GUI, TUI and CLI.
- Python
- llama.cpp
- Qwen3
- CUDA
- Vulkan
- Metal